
The key system design interview habit is to make your reasoning visible before complicating the architecture. Do not start drawing boxes immediately. Agree on the problem, establish constraints, and explain your approach.
Use six steps: clarify requirements, estimate scale, define APIs and data, sketch the architecture, investigate a bottleneck, and explain trade-offs and failure modes. The 45-minute timings are a planning aid, not a universal format; adapt when the interviewer redirects you.
What interviewers are trying to understand#
A system design discussion is not a contest to name infrastructure components. It reveals how you turn an ambiguous request into a coherent design and respond when assumptions change. Interviewers need to follow your problem framing, technical judgment, scale reasoning, trade-off awareness, operational thinking, and communication. Make each visible: state assumptions, connect components to access patterns, compare alternatives against requirements, and explain failure and recovery behavior.
These are useful dimensions to prepare for, not a claim that every interviewer uses the same rubric. For example, Amazon's public system-design preparation page lists practicality, accuracy, efficiency, reliability, optimization, and scalability as objectives for its own process. That is one employer's published guidance, not a universal interview specification (Amazon system design interview preparation).
Mid-level candidates should prioritize a clear end-to-end design. Senior candidates should also expose boundaries, operational costs, failure behavior, and alternatives.
The six steps at a glance#
Use this table as a 45-minute pacing guide. The allocation deliberately reserves time for a meaningful deep dive and a discussion of trade-offs.
| Step | Approx. time | What you should produce |
|---|---|---|
| 1. Clarify requirements | 0–6 min | Prioritized functional and non-functional requirements; explicit scope |
| 2. Estimate scale | 6–10 min | Rough traffic, storage, and workload assumptions that influence design |
| 3. Define APIs and data | 10–16 min | Core request/response contracts, entities, keys, and access patterns |
| 4. Sketch high-level design | 16–25 min | A complete read/write path and the main system components |
| 5. Deep dive on a bottleneck | 25–37 min | One critical component explored through normal and edge-case flows |
| 6. Explain trade-offs and failure | 37–45 min | Alternatives, failure modes, mitigations, and a concise design summary |
Treat the clock as a guardrail. Adapt to interviewer direction; if time runs short, preserve the end-to-end picture and summarize the next deep dive.
Step 1: Clarify requirements before drawing#
Restate the prompt and identify the smallest useful system. Separate functional requirements (what users can do) from non-functional requirements (how well it must behave).
For “design a notification service,” functional requirements might include creating, delivering, and tracking a notification. Non-functional questions could cover latency, ordering, durability, peak volume, and retries.
Ask questions that can change the design:
- “Which user action is the primary flow we need to support?”
- “Is near-real-time delivery required, or is a delay acceptable?”
- “Do we need strict ordering, and what happens during a provider outage?”
- “Can scheduling and analytics stay out of the first version?”
Then summarize the agreement: “I’ll design the create-and-deliver path first, with durable retries. I’ll leave analytics and campaign scheduling out unless we have time.”
This gives the interviewer a chance to correct your scope before you build on it.
Step 2: Estimate scale to expose constraints#
Estimate only enough to expose pressure points: active users, requests per second, read/write ratio, payload size, retention, and peak-to-average traffic where relevant.
For a hypothetical two million notifications per day, the average is about 23 per second. Assuming a five-times peak gives roughly 115 per second. These are exercise assumptions, not industry benchmarks.
Say what the estimate means: “At this volume, a single service and durable database may be enough initially. I would still put asynchronous delivery behind a queue so provider latency does not block the API. If peak traffic grows substantially, queue partitioning and worker concurrency become the next questions.”
Write down assumptions. For storage, use daily writes × average record size × retention, noting whether indexes and replication are included.
Step 3: Define the APIs and data model#
APIs make the contract concrete; data modeling clarifies what must be stored and how it will be retrieved. Cover both before detailing the architecture.
A minimal notification API might look like this:
| Endpoint | Purpose |
|---|---|
| POST /notifications | Accept a notification request and return an identifier |
| GET /notifications/{id} | Read its current delivery status |
A record might contain notification_id, user_id, payload, status, created_at, attempt_count, and next_attempt_at. Query patterns, retention, and privacy requirements determine the final schema and indexes.
Useful phrases include:
- “I’m choosing this endpoint because it maps directly to the create flow we agreed to.”
- “The status field represents delivery state, not proof that the user read the message.”
- “Before choosing a database, I want to confirm the dominant query patterns and consistency requirements.”
Identify the core entities, identifiers, relationships, and access patterns; do not turn this into a full schema-design exercise.
Step 4: Sketch the high-level design#
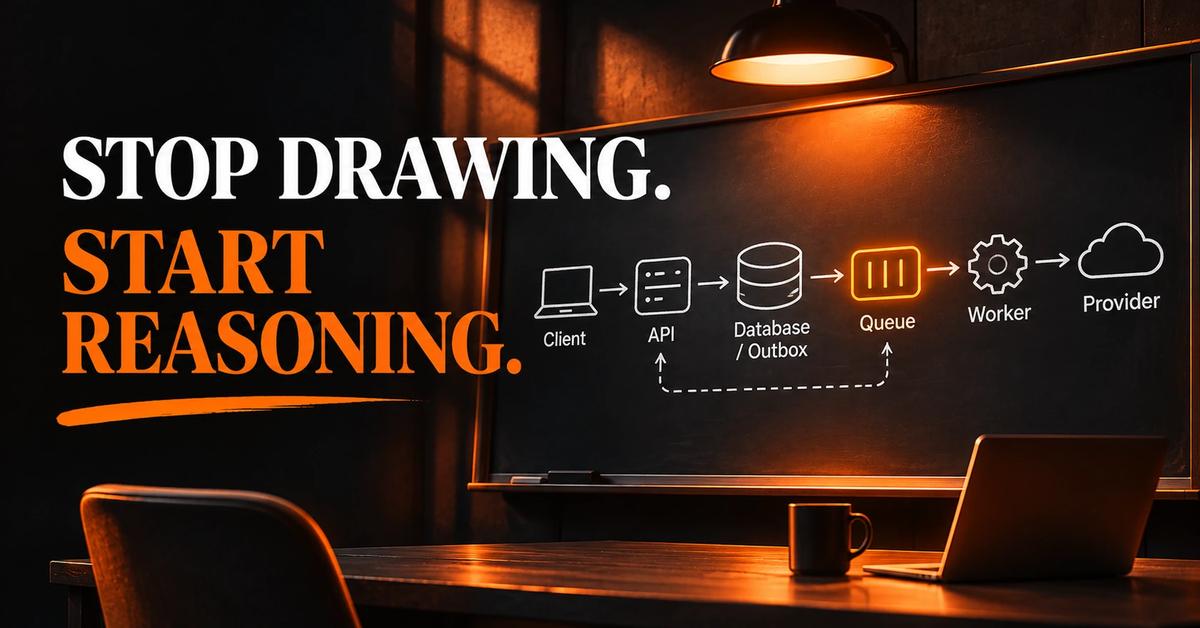
Draw the smallest architecture that satisfies the requirements. For the notification example:
- A client sends a request to an API service.
- The API validates the request and writes a durable notification record.
- The service publishes a delivery job to a queue.
- Workers consume jobs and call the relevant delivery provider.
- Workers update delivery state and schedule retries when appropriate.
- A status endpoint reads the stored state and returns it to the client.
Label components and arrows, and show read/write paths. A “queue” box is not an explanation: state why it exists, what it stores, and what happens if publishing or consumption fails.
Narrate as you draw:
“I’m separating request acceptance from provider delivery. The API can acknowledge a request after it is durably recorded, while workers handle slower external calls. I’ll now check whether the database write and queue publish can fail independently.”
That final sentence exposes a real design question: if the record is committed but the queue publish fails, the notification can remain stuck. You can address it in the deep dive rather than hiding it behind an arrow.
Step 5: Deep dive on the bottleneck#
Do not explain every box equally. Pick the component most likely to threaten a requirement, or ask where the interviewer wants depth. Trace one complete flow, including failure and recovery.
For the notification design, the database-to-queue handoff is a strong candidate. If the database write succeeds and queue publication fails, the record exists but no worker receives it. One option is the transactional outbox pattern: write the notification and an outbox event in the same database transaction, then have a separate publisher relay pending events to the queue. The publisher must handle retries and duplicate delivery; consumers should therefore be idempotent.
Explain the flow in sequence:
- “The notification row and outbox event commit together, so the system does not acknowledge a database-only partial state.”
- “The relay can publish an event more than once if it crashes after publishing but before recording success.”
- “I’ll give each event a stable identifier and make the worker safe to process the same event again.”
- “I would monitor outbox age and queue lag because a growing backlog means accepted work is not being delivered promptly.”
This is a hypothetical walkthrough, not a universal prescription. A simpler design may fit low volume or systems that tolerate reconciliation. Identify the failure window and match the mitigation to the requirements.
Step 6: Discuss trade-offs, failures, and the next constraint#
A design is a set of decisions tied to requirements, with costs made explicit. For each important choice, name an alternative and explain why one fits the assumptions.
| Decision | Option A | Option B | Trade-off to explain |
|---|---|---|---|
| Delivery | Synchronous provider call | Queue and workers | Queue improves isolation and retry control but adds operational complexity and delivery delay |
| Handoff | Direct database + queue writes | Transactional outbox | Outbox closes a dual-write failure gap but adds relay and cleanup work |
| Retry | Immediate retry | Delayed retry with backoff | Backoff reduces pressure during outages but increases delivery time |
| Status | Strongly consistent read | Eventually updated status | Strong consistency can cost more; eventual state needs clear client expectations |
Then test the design against failure cases:
- Provider outage: pause or slow retries, apply backoff, and prevent one failing provider from consuming all worker capacity.
- Duplicate job: use idempotency keys or a processed-event record so a retry does not create an unintended second delivery.
- Queue backlog: monitor lag, scale workers within provider limits, and apply admission control if the system cannot safely accept more work.
- Poison message: cap attempts, isolate the message for inspection, and make redrive deliberate rather than infinite.
- Database degradation: define what the API returns when it cannot durably accept a notification; do not acknowledge work that has not been safely recorded.
Close by summarizing the design and its remaining risks: “The core path is durable acceptance followed by asynchronous delivery. The main complexity is the database-to-queue handoff and duplicate processing. I would validate throughput under peak load, provider rate limits, and the recovery process for messages that exhaust retries.”
That summary demonstrates ownership of the design without pretending every implementation detail has been solved.
A worked walkthrough: design a notification service#
Prompt: Design a service that accepts application notifications and delivers them to users.
1 — Clarify. “I’ll focus on accepting a notification, delivering it through one provider, and exposing delivery status. Can scheduling and analytics stay out of scope?” The interviewer agrees and emphasizes durable delivery.
2 — Estimate. “I’ll assume two million notifications per day: about 23 per second on average. With a five-times peak assumption, that is roughly 115 per second. I’ll revisit the estimate if the workload changes.” These are hypothetical numbers for the exercise, not industry benchmarks.
3 — Define APIs and data. “The create endpoint returns an ID after durable acceptance. The status endpoint reports pending, delivered, or failed. I’ll store the notification, delivery state, timestamps, and an event identifier.” The candidate confirms whether status must be immediately consistent.
4 — Sketch. Draw client → API → database/outbox → publisher → queue → workers → provider, plus the status read path. “The queue isolates provider latency from request handling. The outbox makes the database-to-queue handoff the next risk to examine.”
5 — Deep dive. “If the database write succeeds but queue publication fails, accepted work can become stuck. I’ll write the notification and outbox event in one transaction, then relay pending events. The relay can publish twice, so workers must be idempotent.” Trace a crash before publication, a crash after publication, and a provider timeout.
6 — Trade-offs and failure. Compare the outbox with direct publishing, delayed retries with immediate retries, and eventual status updates with stronger consistency. “The main remaining risks are provider limits and recovery after repeated failures. I would validate throughput, queue lag, and the redrive process.”
The example is bounded. If the interviewer changes the workload or delivery guarantee, return to the affected requirement and revise the relevant decisions rather than restarting the whole design.
Common mistakes—and how to recover#
| Mistake | Recovery phrase or action |
|---|---|
| Drawing boxes immediately | “Before I commit to a design, I want to confirm the primary user flow and the most important constraint.” |
| Asking too many low-impact questions | State a reasonable assumption, mark it, and move on: “I’ll assume X for now; we can revisit it if it changes the design.” |
| Naming technologies without a reason | Tie each component to a requirement or access pattern. If there is no reason, remove it. |
| Over-engineering for hypothetical scale | Start with the smallest credible design, then identify the first scaling limit. |
| Going deep before showing the whole system | Pause and sketch the end-to-end read/write path; return to the component afterward. |
| Treating pushback as failure | “That changes the consistency requirement. Let me trace which parts of the design need to change.” |
| Running out of time | Summarize the working design, the unresolved risk, and the next deep dive rather than adding disconnected boxes. |
When an assumption changes, state the new constraint, identify the affected component, and explain the revised decision.
How to practice: alone, with a partner, or with AI#
Practice the process, not just a finished architecture. Memorizing one design does not prepare you for changed requirements.
Alone: Pick a prompt, set a 45-minute timer, and record yourself explaining the design. Spend the first pass on the six-step sequence. Review the recording for unanswered requirements, unexplained arrows, missing failure paths, and decisions without alternatives. Repeat the same prompt with one changed constraint, such as stronger consistency or a much higher read ratio.
With a partner: Ask the other person to act as an interviewer. They should clarify the prompt only when asked, challenge assumptions, and introduce one changed requirement midway through. Review whether the design was understandable and whether the candidate adapted to new information.
With an AI interviewer: Use an AI tool to generate prompts, keep time, ask follow-up questions, and critique the explanation against a rubric. Give it explicit instructions not to reveal a complete solution too early. Treat its feedback as practice input, not an authoritative assessment. Verify important decisions independently and seek human review when possible.
A practice prompt should specify role level, duration, a requirement change, and a rubric for scope, estimates, API/data design, architecture, trade-offs, failures, and communication. The AI Prompt Pack for Job Seekers includes a rehearsal prompt (prompt 19).
What to do next#
Use the System Design Cheat Sheet as a compact reference while practicing. Choose one prompt, follow the six steps, and finish by explaining the biggest trade-off and the first failure mode you would investigate.
The goal is a sequence of defensible decisions another engineer can follow and challenge—not the most complicated diagram.
References#
- SDM Interview Prep — Amazon Jobs — public, employer-specific system-design objectives; used only as an example of published evaluation language, not as a universal rubric.

Software Engineer and Researcher, writing about AI, developer tooling and automation.