Research Radar
8 articlesWe read the paper so you can judge it: the question, the method, what was found, the limitations that matter, and what it could mean for your work. Preprints and vendor research are labeled as such.
Featured in Research Radar
Model Distillation for Engineering Leaders: When a Smaller Model Is the Right Call
Model distillation transfers a larger model's task-relevant behavior into a smaller student. Research demonstrates meaningful efficiency gains in defined settings, but not a universal replacement for the teacher.

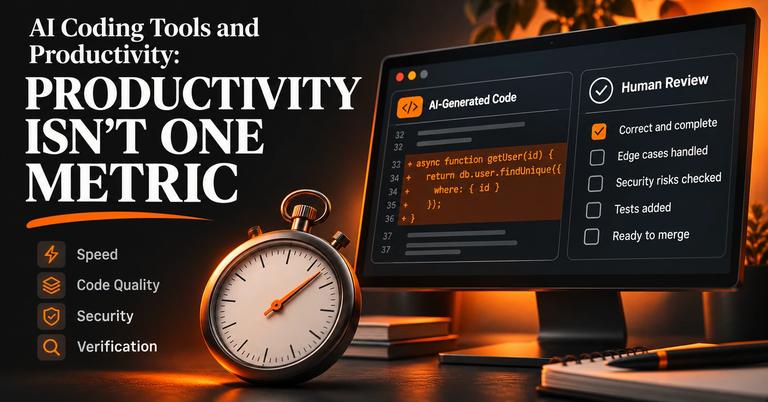
AI Coding Tools and Productivity: What the Research Actually Found
AI coding research does not produce one productivity verdict. Controlled trials, repository analyses, security tests, and developer surveys measure different outcomes—and their limits matter.
All Research Radar articles
Newest first.
Model Distillation for Engineering Leaders: When a Smaller Model Is the Right Call
Model distillation transfers a larger model's task-relevant behavior into a smaller student. Research demonstrates meaningful efficiency gains in defined settings, but not a universal replacement for the teacher.
AI Coding Tools and Productivity: What the Research Actually Found
AI coding research does not produce one productivity verdict. Controlled trials, repository analyses, security tests, and developer surveys measure different outcomes—and their limits matter.
Does Size Matter? Bigger AI Isn’t Always Better
Does size matter? There. I asked it. Humanity has spent an unreasonable amount of time arguing about this question, so naturally we eventually gave the problem to artificial intelligence. Except now we measure it in billions of parameters .
A Tool Result Is Evidence, Not Ground Truth
Connecting an agent to a database does not remove hallucination risk. It gives the system a second source that can be stale, malformed, unauthorized, or simply wrong—and a protocol that may make the model trust it more than it should. Tools
Benchmark the Model–Harness Pair, Not the Model
“Which model is best for coding?” sounds like a precise engineering question. Usually, it is missing half of the system. A coding agent is a model inside a harness that chooses tools, assembles context, serializes results, decides when to
Your Agent Passed the Eval. Its Retrieval Calls Still Tripled.
An AI agent can pass the task and still fail the engineering evaluation. That happens when a context-compression policy preserves the final outcome but changes how the agent gets there. The agent still completes the benchmark. It also
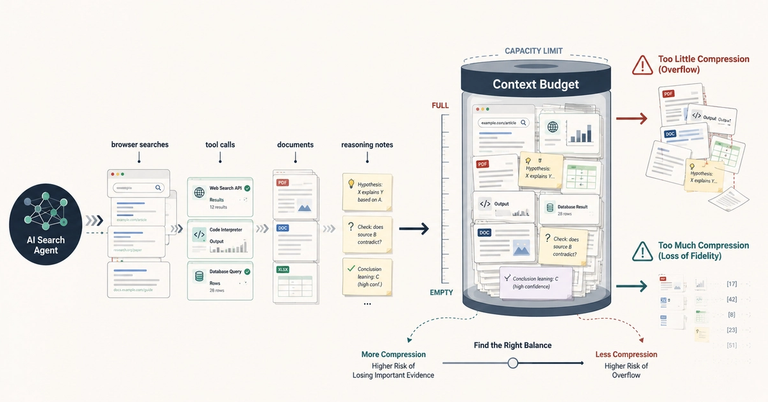
AI Agents Do Not Just Need More Context. They Need a Context Budget
A long context window sounds like an obvious advantage for an AI agent. The agent can retain more search results, tool outputs, intermediate reasoning, and evidence. Give it enough context, and perhaps it will stop forgetting what it
Is Overthinking a Red Flag? We Put AI Reasoning to the Test.
More Thinking Doesn't Always Mean Better Answers Reasoning models are designed to think step by step, and the common assumption is simple: More thinking = better results. I expected reasoning models to dramatically outperform simpler ones.