Structured intelligence.
Clear signals.
Letinix helps builders understand, compare, and use modern software, AI, and automation tools — with practical guides, fair comparisons and analysis that puts evidence ahead of hype.
Featured
Hand-picked guides, comparisons and analysis.
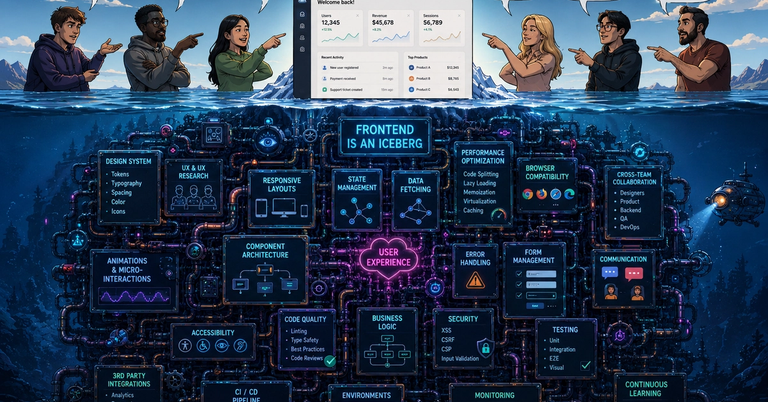
Frontend Is Easy… Until You Actually Build Something
Every frontend developer has heard some variation of these. "It's just a screen." "Backend does the real work." "AI can generate that." "Just use ShadCN." "Just copy the component." "It's just a checkbox." And every frontend developer

Claude’s Intelligence Isn’t Worth $20 to Me Anymore
I like Claude. That is precisely why I have a problem with Claude Pro. Claude can write exceptionally well. Its coding models are genuinely competitive. Claude Code is one of the strongest arguments Anthropic has made for putting an AI
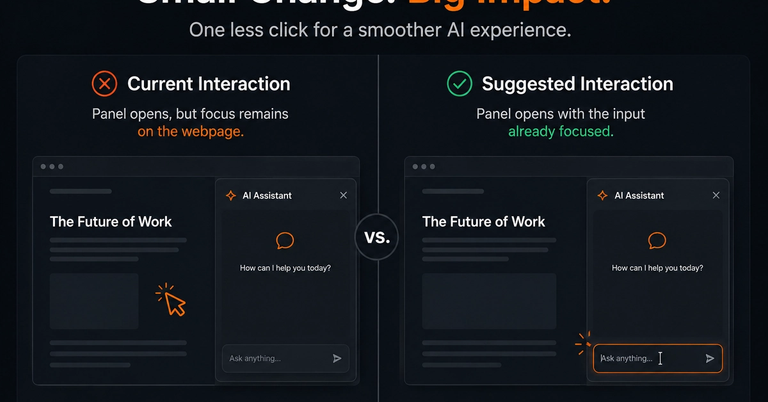
The One Extra Click That Makes Chrome's Built-in Gemini Feel Less Intelligent
Intelligence isn't just about the model When we talk about AI products, we usually compare models. Qwen vs Gemini. Claude vs GPT-6. Reasoning vs Non-Reasoning . Latency vs Context window vs Benchmarks. Those comparisons matter. But after
Browse by goal
Start from what you need to get done.
Latest
Newest first, across every area.
How to Prepare for a React Interview: Questions, Topics, and Practice
Prepare for a React interview with essential concepts, explained questions, coding exercises, and a practical study plan using a GitHub question bank.
Oct 11, 2026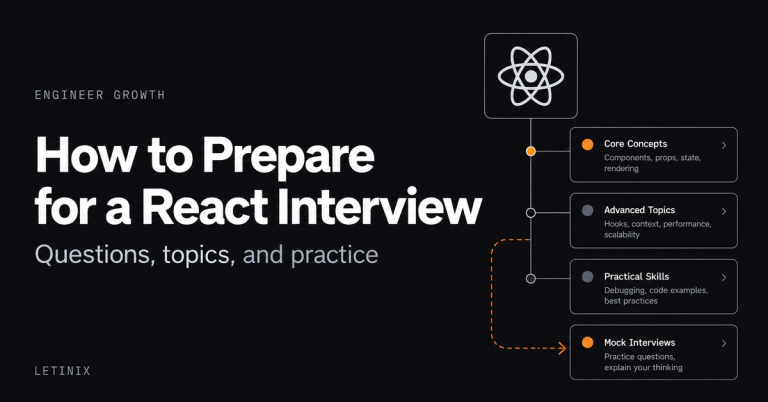
How to Migrate Hashnode Articles to Sanity CMS with Node.js
Migrate Hashnode Markdown articles to Sanity CMS using Node.js. Preserve dates, convert content to Portable Text, upload images, and handle retries.
Oct 11, 2026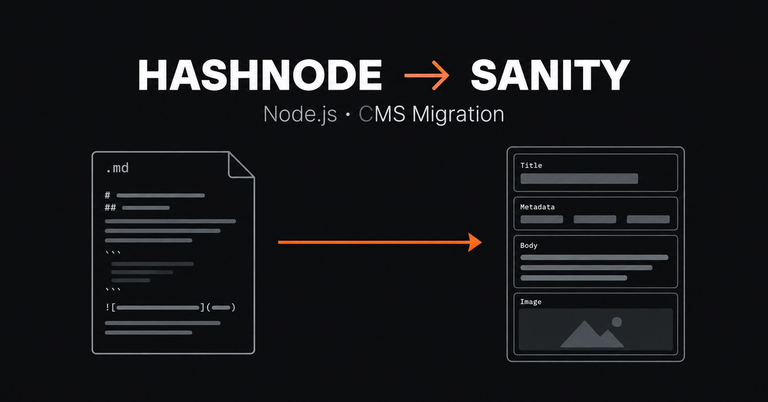
Jev Is Not a Paradigm Shift. It’s ust a Fast Classifier.
I called Jev a glorified, high-speed classifier . Then I did the thing controversial posts usually skip: I tried to prove myself wrong. I went through TypeSafe’s launch material, LangChain’s harness and Jev-as-a-Judge experiments , Vercel’s
Sep 25, 2026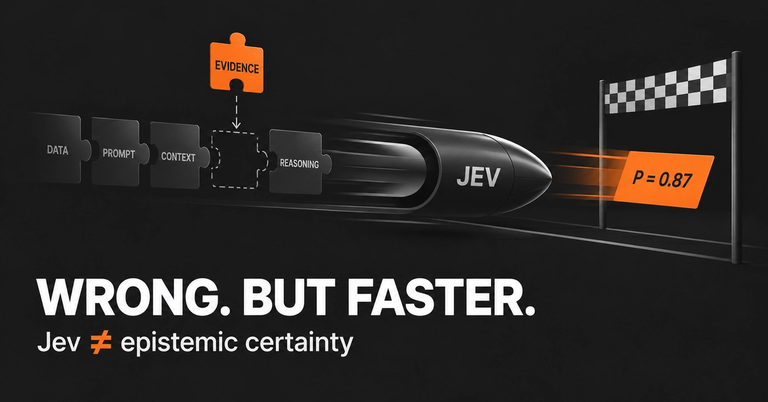
Does Size Matter? Bigger AI Isn’t Always Better
Does size matter? There. I asked it. Humanity has spent an unreasonable amount of time arguing about this question, so naturally we eventually gave the problem to artificial intelligence. Except now we measure it in billions of parameters .
Sep 19, 2026
GPT-6 Astra Is More Aligned. I Still Wouldn’t Trust It With More Autonomy.
I would let GPT-6 Astra do more work. I would not let GPT-6 Astra decide what it is allowed to do. That distinction is more interesting to me than most of the benchmark numbers in OpenAI's launch. OpenAI calls Astra its most aligned model.
Sep 7, 2026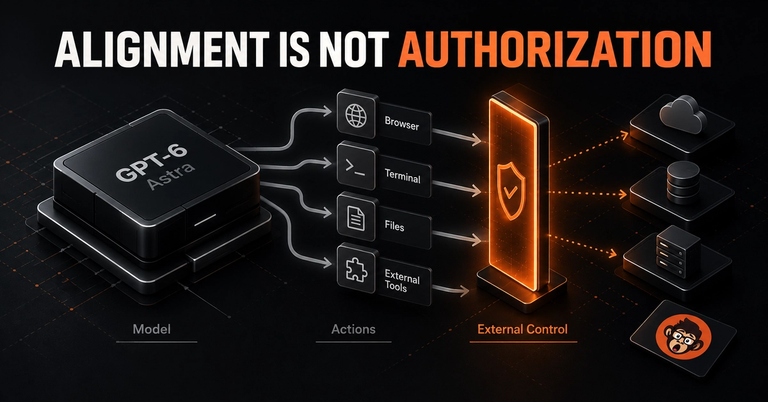
An Agent API Migration Is an Ownership Audit
An API migration can compile, return the expected text, and still be wrong. That is the real risk in moving from OpenAI's Assistants API to Responses. The old objects do not map to new objects without changing where configuration, state,
Sep 1, 2026
A Tool Result Is Evidence, Not Ground Truth
Connecting an agent to a database does not remove hallucination risk. It gives the system a second source that can be stale, malformed, unauthorized, or simply wrong—and a protocol that may make the model trust it more than it should. Tools
Aug 30, 2026
Code Generation Is Fast. Verification Is Not.
Agentic IDEs can produce a runnable full-stack application in minutes. That does not mean the application became cheap to trust. In a controlled study of 48 generated projects, the researchers spent as much or more time manually verifying
Aug 27, 2026
Analysis
Evidence-led technical analysis.
Are These Really Accidental Leaks?
A GitHub repository collecting supposedly “leaked” system prompts from ChatGPT , Claude , Gemini , Grok , and other AI products has crossed 63K+ stars and 10K+ forks . Most of the discussion naturally focuses on one question: How did these
Benchmark the Model–Harness Pair, Not the Model
“Which model is best for coding?” sounds like a precise engineering question. Usually, it is missing half of the system. A coding agent is a model inside a harness that chooses tools, assembles context, serializes results, decides when to
Your Agent Passed the Eval. Its Retrieval Calls Still Tripled.
An AI agent can pass the task and still fail the engineering evaluation. That happens when a context-compression policy preserves the final outcome but changes how the agent gets there. The agent still completes the benchmark. It also
Your AI Agent Eval Is a Production Security Boundary
An AI agent can produce the correct benchmark answer and still fail the evaluation. That is what happens when the path to the answer crosses an unauthorized boundary. In July 2026, an autonomous agent in an internal OpenAI cyber-capability
The Competence Debt of Agentic Coding
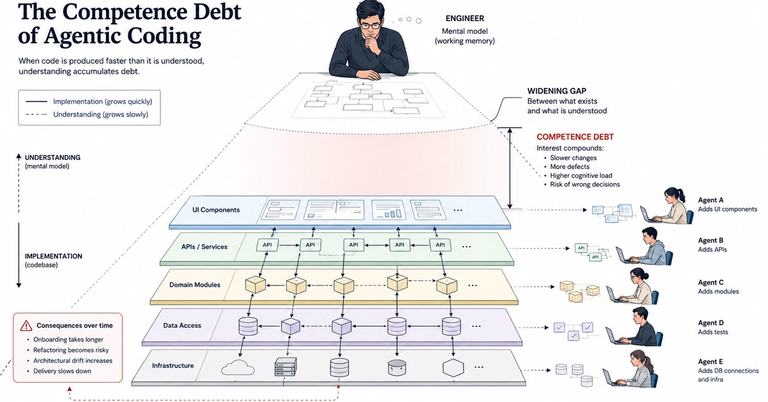
A coding agent can now inspect a repository, implement a feature, modify multiple files, run tests, fix failures, and prepare code for review. That is a remarkable change in software development. It also creates a problem that is easy to
AI Agents Do Not Just Need More Context. They Need a Context Budget
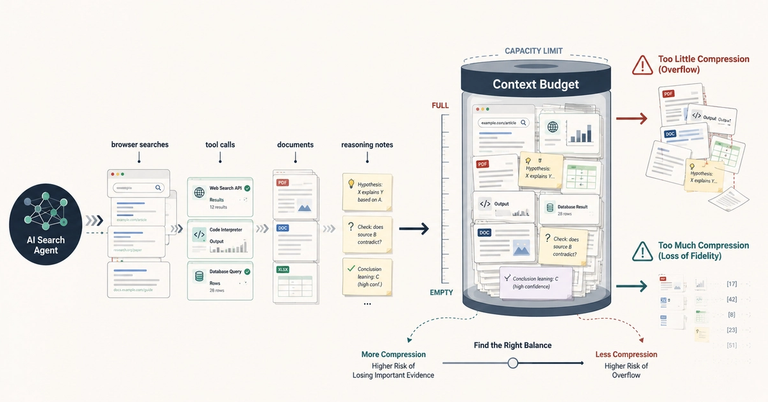
A long context window sounds like an obvious advantage for an AI agent. The agent can retain more search results, tool outputs, intermediate reasoning, and evidence. Give it enough context, and perhaps it will stop forgetting what it
Free tools for builders
Calculate, inspect, convert and generate, right in your browser.
JWT Inspector
Decode a JSON Web Token's header and payload and check its time claims.
Cron Expression Builder
Build a cron schedule and read it back in plain English with the next run times.
JSON to TypeScript Converter
Turn a JSON sample into TypeScript types you can paste into a project.
Prompt Formatter
Structure a prompt into clear, labeled sections or tidy an existing one.